Back to home
🌐 Emojify
Bidirectional emoji-text translator powered by embedding-based semantic search
A CLI tool that translates between natural language and emoji sequences using OpenAI's ada-002 embeddings. Type a sentence and get the perfect emoji sequence; paste emoji and get the intended message back. Under the hood, it maps both modalities into a shared 1,536-dimensional vector space — the same cross-modal search principle behind CLIP and multimodal retrieval systems — applied at a scale where every step is inspectable.
🛠️ Tech Stack
🚀 Features
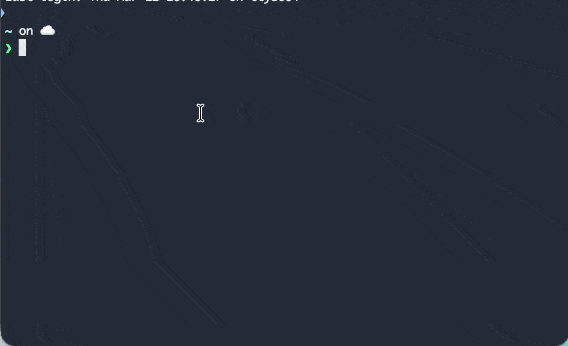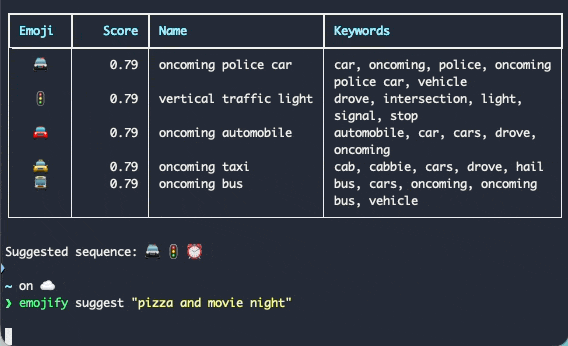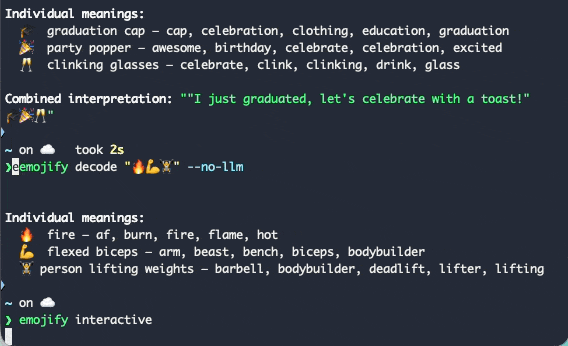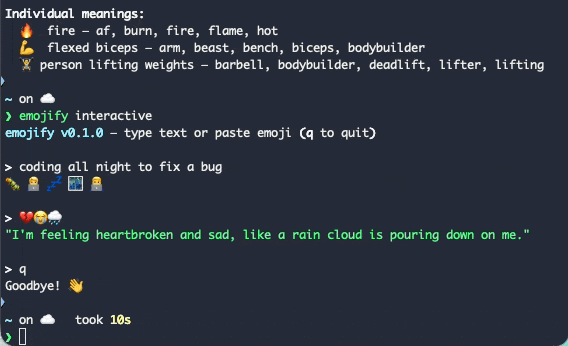
Text → Emoji: embed a natural language query and rank ~1,800 emoji by cosine similarity in <5ms using brute-force NumPy — no vector database needed at this scale
Emoji → Text: two-stage pipeline — deterministic metadata lookup (handles ZWJ sequences, flag pairs, skin-tone modifiers) followed by GPT-3.5 Turbo interpretation
Two-pass diversity filter that prevents redundant results (e.g., five identical smiley faces) by enforcing one emoji per Unicode category, with automatic relaxation when categories are sparse
SQLite embedding cache eliminates redundant API calls across sessions — zero external dependencies beyond the stdlib
Interactive REPL with auto-detection of input type (text vs. emoji) for rapid bidirectional exploration
Four-stage data pipeline (
fetch → merge → describe → embed) that combines Unicode CLDR and Emojilib into richly described, template-augmented embeddings for ~$0.02 total build cost
🧗♂️ Challenges
Discovered that embedding raw keyword lists scored significantly worse than embedding template-augmented descriptions — context engineering (
'pizza — commonly used to express: cheese, food, hungry') outperformed model selection for retrieval qualityOpenAI SDK v1.0 uses
httpxconnection pools that hang short-lived CLI processes; diagnosed the thread lifecycle issue and replaced single-embedding calls with directurllibrequests while keeping the SDK for batch operationsDesigned a two-pass diversity filter to handle conflicting requirements — strict category deduplication for common queries vs. relaxed backfilling for deep-category queries like 'sushi dinner' where most results share Food & Drink
Built a 50-case evaluation suite across 10 semantic categories revealing that concrete nouns average 2.7+/3.0 while abstract emotions and sarcasm average ~2.0 — quantifying exactly where embedding-based search hits its limits
🧠 Learnings
What you embed matters more than which model you use — template-based description augmentation improved retrieval quality more than any other single change, a lesson that carried directly into later RAG projects
Right-sizing infrastructure is an engineering skill: 1,800 vectors × 1,536 dimensions fits in 14MB of RAM and searches in <5ms with brute-force NumPy — a vector database would add operational complexity for zero performance gain
Cross-modal semantic search is just regular search in the right embedding space — building this at small scale made the CLIP / multimodal retrieval principle concrete before needing it in larger systems
Even for a fun side project, a scored evaluation suite caught failure modes (sarcasm, abstract emotions) that manual spot-checking completely missed — this discipline became the foundation for later evaluation work